 Analytics & Measurement
The Analytics Audit: Is Your Data Telling Truth?
Jul 20, 2021
· 4 min read
Log files show exactly how crawlers hit your site - no sampling, no estimation. What they reveal, why they matter for larger sites, and how to approach the analysis.
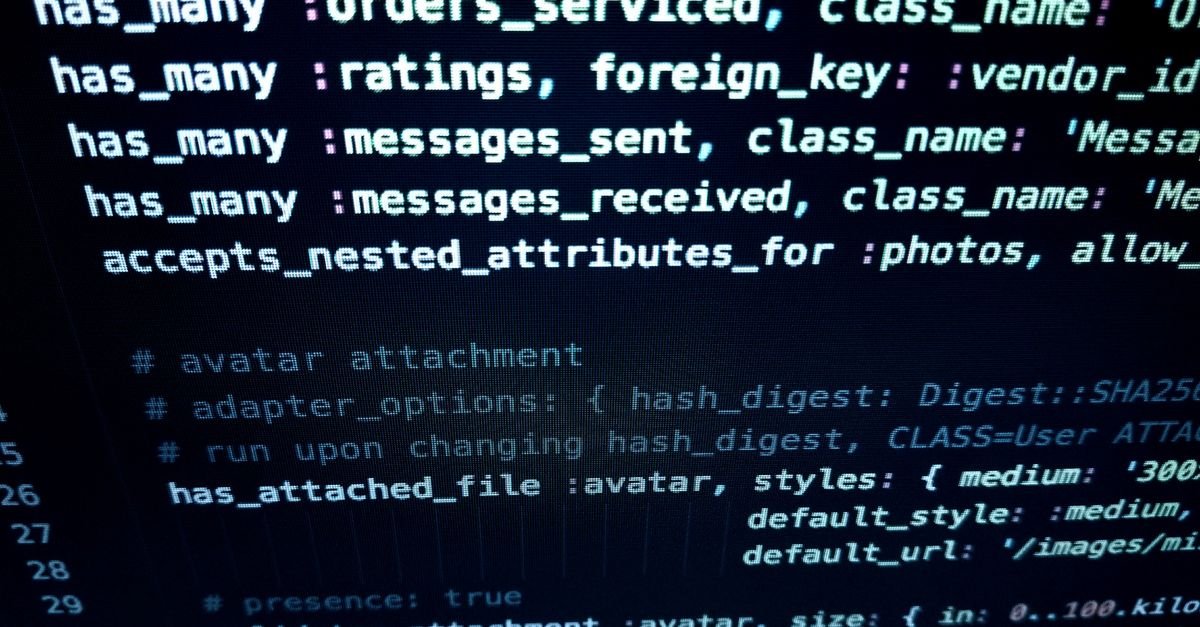
Log file analysis is the most direct, unfiltered way to see how search engine crawlers actually interact with your site — because your server logs record every real request Googlebot makes, no sampling, no JavaScript, no estimation. For technical SEO on larger sites, it reveals crawl behaviour that no other tool can show: exactly what Google crawls, how often, and where it wastes effort. Here's what log analysis reveals, why it matters, and how to approach it.
The unique visibility logs provide: your server logs record every request — including every hit from Googlebot and other crawlers — as it actually happened, giving you the ground truth of crawl behaviour that estimated tools can't match. From logs you can see: what Google actually crawls (which URLs Googlebot requests — versus what you think it crawls), crawl frequency (how often it visits pages — your important pages should be crawled regularly; if they're rarely hit, that's a problem), crawl budget waste (Googlebot spending requests on low-value URLs — parameter variations, duplicates, dead ends — instead of your important content, the crawl-budget leak), crawl errors (the status codes Googlebot actually receives — real 404s, 500s, redirects it hits), and crawl timing and patterns (how Google's crawling responds to your changes). This is the real crawl behaviour, not a tool's approximation of it.
The value and its scope: log analysis matters most for larger sites where crawl budget is real — on a big site (thousands to millions of URLs), Google won't crawl everything, so where it spends its crawl budget determines what gets indexed and how fresh your index stays, per the crawl-budget logic. Logs let you: find and fix crawl waste (stop Googlebot wasting budget on junk URLs so it spends more on your important content), verify important pages get crawled (confirm your money pages are visited regularly, not neglected), diagnose indexing issues (a page not indexed — is it even being crawled? logs answer definitively), and catch crawl problems tools miss (the real status codes and behaviour, not estimates). For a small site, crawl budget rarely constrains anything and log analysis is overkill; for a large or complex site, it's one of technical SEO's most powerful diagnostics, complementing the technical audit.
The practical method: get your server logs (access logs from your server/CDN — the raw request records); filter to verified search crawlers (isolate genuine Googlebot — verify by reverse DNS, since user-agent alone is spoofable — to analyse real search crawl behaviour, per the fake-traffic awareness); use log analysis tools (dedicated log analysers, or import to a data tool — raw logs are huge, so tooling makes them analysable); look for the key patterns (crawl distribution across your URLs — is budget going to important pages? — error rates, crawl frequency of key pages, and waste on low-value URLs); and act on findings (block/noindex/consolidate the crawl-waste URLs, fix the errors Googlebot hits, ensure important pages are crawlable and internally linked — the fixes that redirect crawl budget to what matters, per the crawl-budget optimisation). Log analysis turns crawl behaviour from guesswork into ground truth — the deepest view of how search engines engage the content and authority you build (our half).
The ground truth of crawl behaviour — exactly what Googlebot actually requests, how often, and what status codes it receives, with no sampling or estimation (your server logs record every real request). Other tools estimate or crawl-simulate; logs show what genuinely happened. This reveals real crawl-budget allocation, whether important pages get crawled, actual crawl errors, and waste — the unfiltered crawl reality, per the crawl-budget analysis.
Mainly if you have a larger or complex site where crawl budget matters (thousands+ of URLs). For a small site, Google crawls everything easily and log analysis is overkill — the technical audit and Search Console's crawl stats suffice. For large sites, though, log analysis is one of the most powerful diagnostics for ensuring crawl budget goes to your important content rather than being wasted.
Get access logs from your server or CDN (the raw request records), filter to verified search crawlers (confirm genuine Googlebot by reverse DNS — user-agent is spoofable), and use log-analysis tools (raw logs are huge, so dedicated tooling makes them workable). Then look for crawl distribution (is budget hitting important pages?), errors, and waste — and act by blocking/consolidating junk URLs and fixing errors, redirecting crawl budget to the content and authority that matter (our lane).
Every site on BacklinksMedia is verified, priced upfront and ready to order.
Growth engineer at BacklinksMedia, working on outreach analytics and the verified link marketplace.
Analytics & Measurement
 Analytics & Measurement
 Analytics & Measurement